Kyle Dunkerley
Open to roles

In Melbourne.

Connect or message

Infrastructure leader · Melbourne
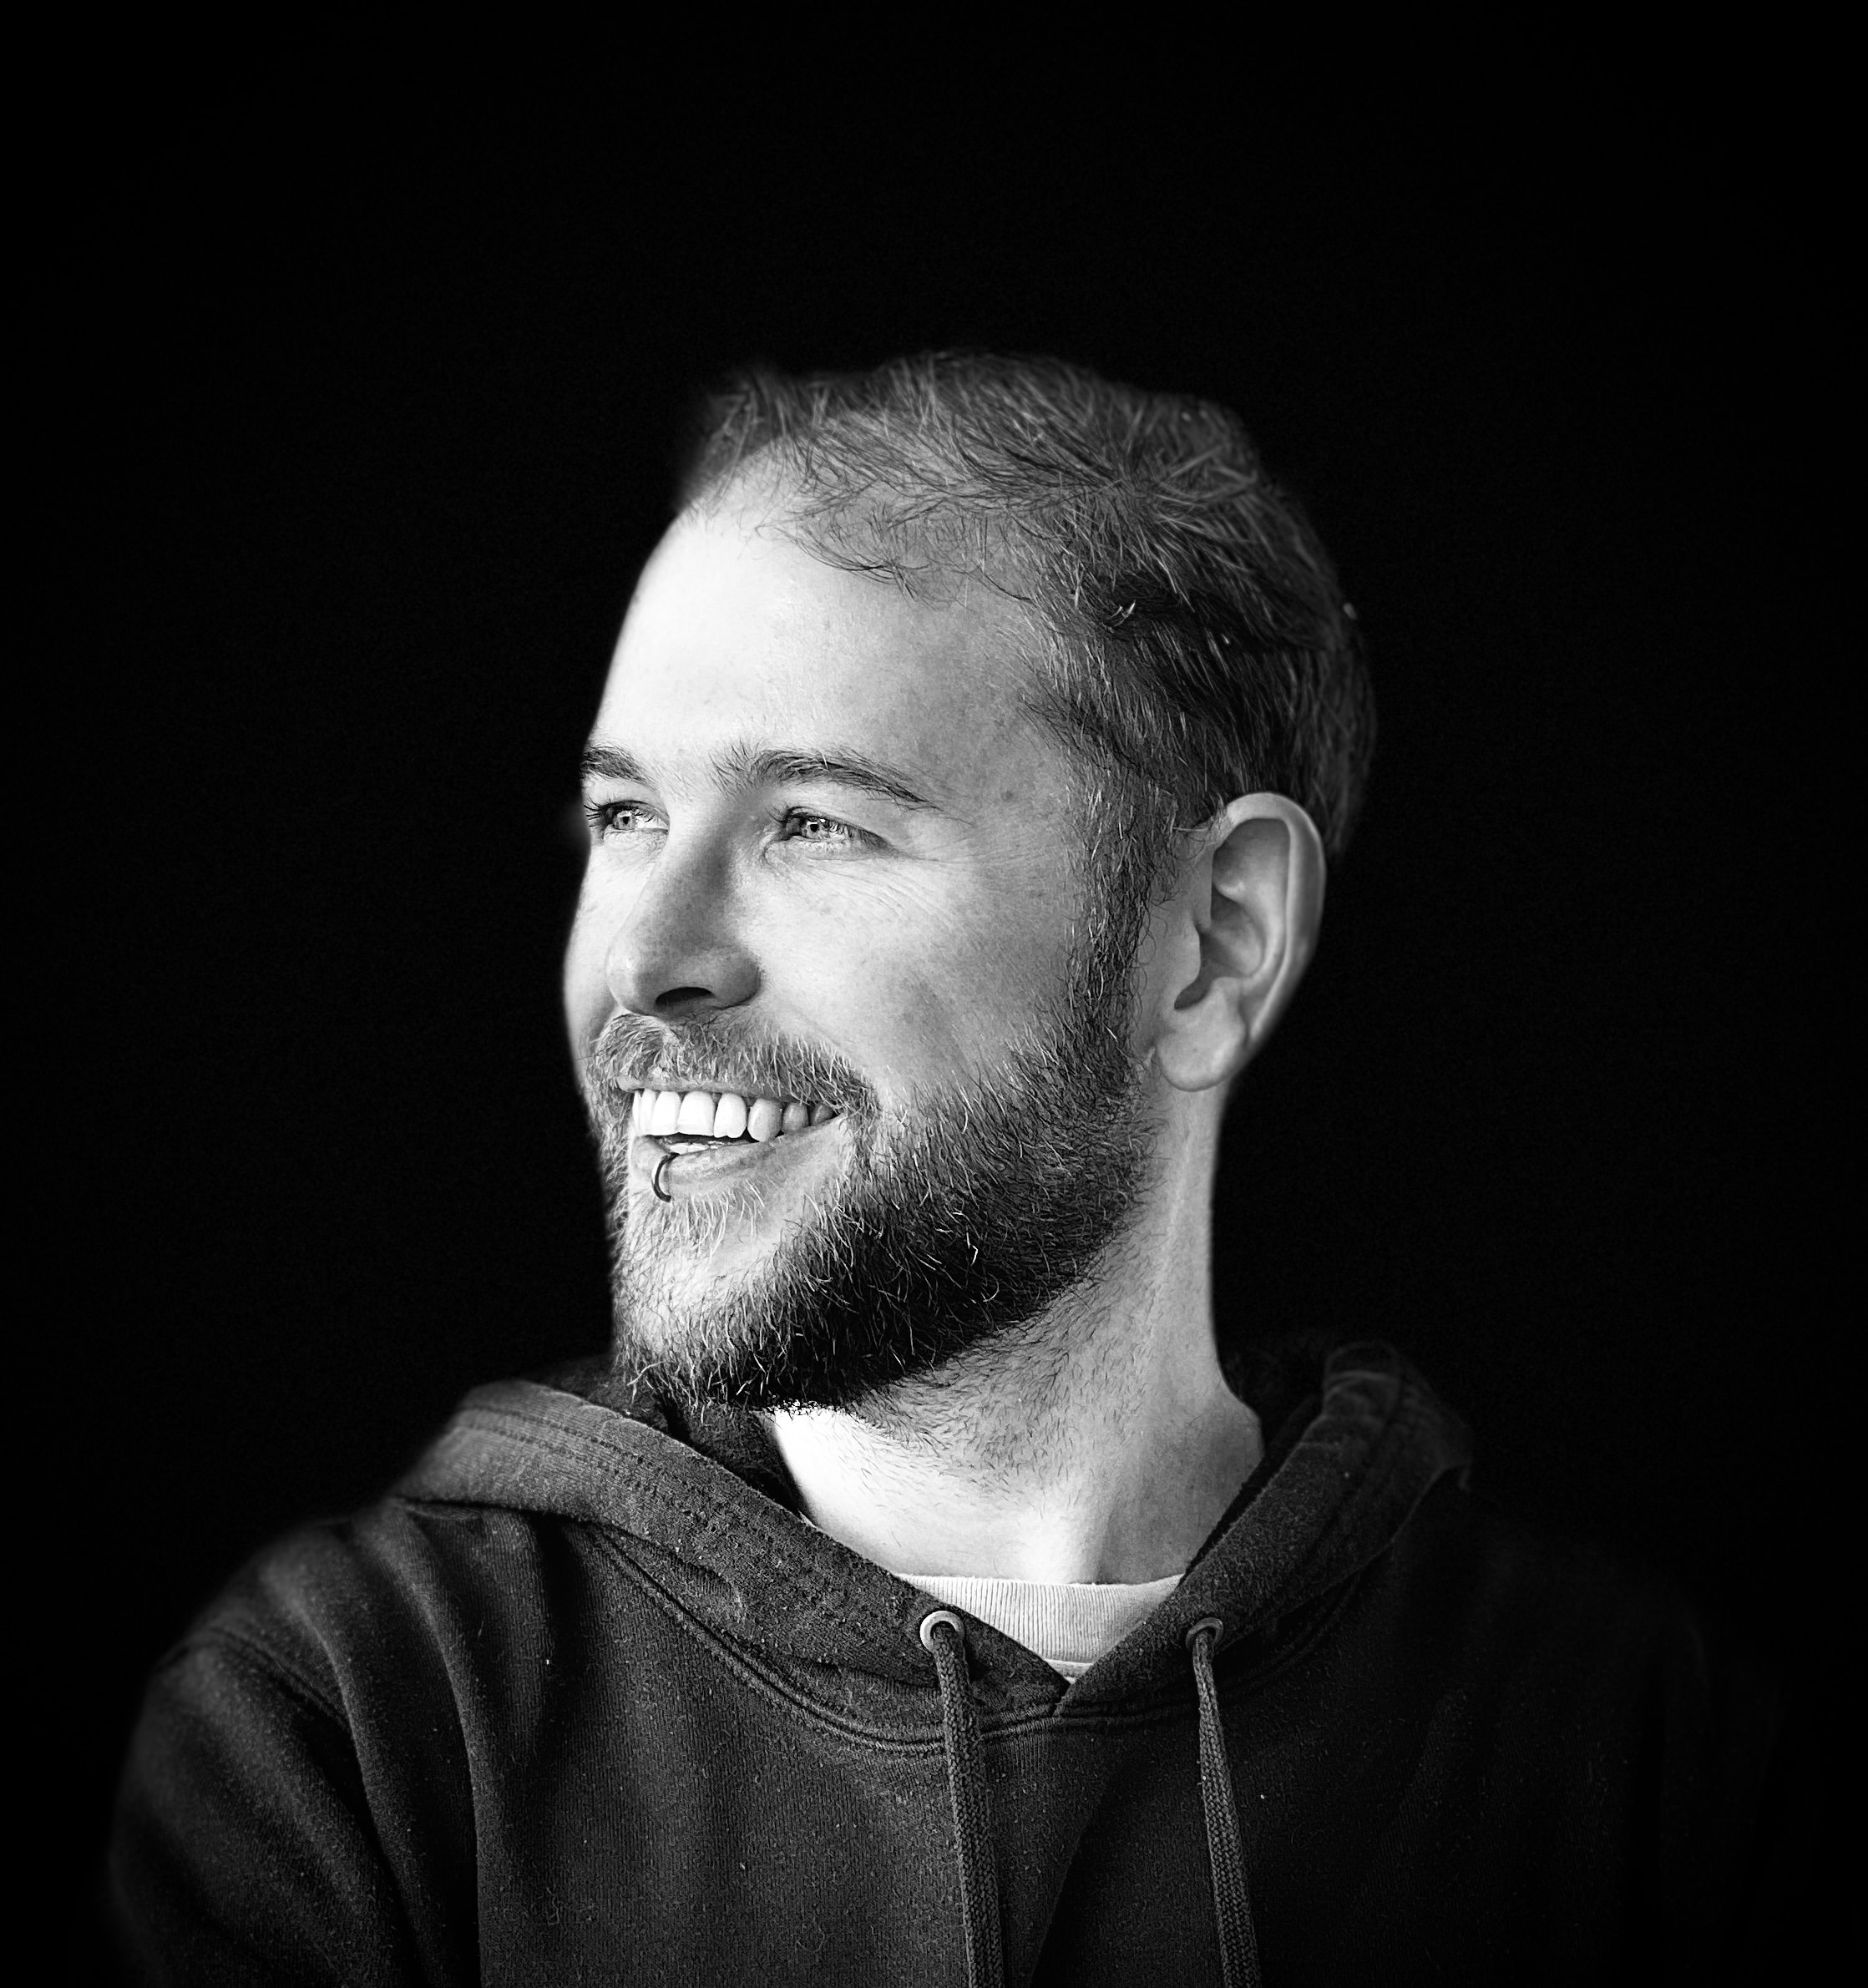
Kyle Dunkerley

Kyle
Dunkerley

I build capable teams and dependable infrastructure.

Associate Manager, Infrastructure Services · DXC Technology

Path · scope grows with every step
  1. 2007LAN AdministratorKwaZulu-Natal, South Africa200+ lab PCs
  2. Mar 2011NOC to on-site supportProphecy Networks, NZSupport, AD, Microsoft 365
  3. 2018Microsoft Solutions SpecialistProphecy Networks, NZIdentity and access
  4. Aug 2019System AdministratorLANtech / Spark, NZMany small clients
  5. 2021–2026WinTel Admin → Team LeadDXC Technology, Melbourne4 engineers, 200+ servers
  6. 2026 → nowAssociate ManagerDXC Technology200+ servers · 6,000+ users
What I’m looking for

What I’m looking for

An internal infrastructure or IT operations leadership role in Melbourne, with responsibility for the people, the platform and its direction.

The responsibility I want to take on

  1. 1
    People

    Help engineers grow into ownership.

  2. 2
    Platform

    Make day-to-day operations dependable.

  3. 3
    Direction

    Connect the roadmap to what the organisation needs.

Right now

I’m looking for an internal IT role with responsibility for both the platform and the people who run it. I’ve led engineers since August 2021, balancing the ticket queue with migrations, lifecycle work and the time people need to learn. I want to bring that experience to infrastructure or IT operations management in Melbourne.

The work that interests me

Give me an estate that needs a clear direction and a team that wants to improve it. I enjoy making the roadmap practical: deciding what needs attention first, explaining why it matters, and helping engineers take ownership of the work.

How to reach me

Connect or message me on LinkedIn to talk about a role, the team behind it and the problems you want to solve.

Hybrid estate

A hybrid estate I’m accountable for

Azure and on-premises, running for people in Australia and New Zealand. My job is that it keeps running and keeps getting easier to run.

Commercial judgment within my remit

4vCPUs per VM
2vCPUs per VM

Three Azure VMs resized after their workload reduced.

A completed capacity change. I don’t currently own a budget, and I’m not claiming a measured dollar saving.

What I own

My remit covers server reporting, the Level 3 server and infrastructure queue, and part of the Azure environment. I’m the senior escalation point for Level 3 and 4 incidents. That means balancing immediate service needs with the lifecycle and maintenance work that keeps the estate dependable.

How it’s run

Changes go through the change advisory board, incidents are followed by written root cause reports, and disaster recovery is tested every six months. Those routines turn availability from an expectation into work we can plan, review and improve.

Recovery in practice

I’ve used Veeam to restore files and shared-drive permissions. Recovery includes getting people back to the right information with the right access. I work with stakeholders and service providers to coordinate that work and keep responsibilities clear.

Capacity with a reason

When the workload on three Azure VMs reduced, I completed a change from four to two vCPUs per machine. I don’t currently control a budget. My contribution here was matching the infrastructure to the work it still needed to do, through the change process.

How I keep it healthy

Lifecycle work has included upgrades from Server 2012 to 2022 and 2025. We monitor with SolarWinds, ManageEngine and scripts, and moved patching from WSUS to ManageEngine Patch Manager. My focus is making maintenance visible, repeatable and something the team can own.

Choosing a current platform

I’ve set Windows Server 2025 as the direction for new deployments rather than continuing with 2022. Some application teams pushed back because it meant more compatibility testing. I explained the lifecycle and security reasons for staying current, and the overall response was accepting.

What I would rebuild

I’d like to modernise a business application currently delivered through an RDS farm in Azure. I would assess Azure Virtual Desktop, managed database options such as Azure SQL serverless, and availability across zones. Those are design goals for a future rebuild, subject to application compatibility and recovery testing; the aim is better responsiveness and fewer interruptions.

Less infrastructure to maintain

I’d also assess Azure Files with DFS namespaces so people have a consistent route to their files, while reducing the Windows servers we maintain just to host shares. For Hyper-V hosts, I’d prefer Server Core where supported. Each change should reduce routine upkeep without making support or recovery harder.

Team

Four engineers, one team

Two on site and two in the Philippines, all working the same estate. I set priorities, take the hardest escalations, and try not to be the only person who can.

One engineer’s progression

  1. 1
    Service desk

    Joined without server experience.

  2. 2
    Guided responsibility

    Step-by-step mentoring in the server environment.

  3. 3
    Owns patching

    Now runs the patching process end to end.

Where I sit

I report to the EUC and WinTel Manager and act as second in command across end-user computing and Windows servers. The team works across on-site and offshore delivery, so priorities and documentation need to make sense wherever someone is working.

How we work

Weekly sprints and a shared Kanban board beside the ticketing system. Living OneNote documentation instead of scattered document versions, plus runbooks, as-built designs and incident reports.

How people grow

A Level 2 service desk engineer in the Philippines joined with no server experience. I mentored him step by step, and he now owns patching end to end in ManageEngine Patch Manager. I also teach Azure, Infrastructure as Code, and how to draft scripts with AI, then review and test them.

Earning trust

Earning the team’s trust was harder than putting the team together. As a younger lead, I had to show experienced colleagues what I could contribute. I laid out a methodical roadmap, followed through on the work and kept making the case that we could improve our part of the estate. Trust grew through that consistency.

Toolkit

The tools, and automation the team can read

I’m pro AI where it makes the work better: faster investigation, a stronger first draft and more room for engineers to solve difficult problems. The aim is to grow what the team can do.

Tools grouped by the work

Identity & access
Active Directory · Entra ID · Microsoft 365
Compute & recovery
Azure · Hyper-V · VMware · Veeam
Repeatable delivery
PowerShell · Bicep · ARM
Operational visibility
SolarWinds · ManageEngine · ServiceNow

The problem and the fix

Deployments leaned on advanced PowerShell only its author could safely change. I moved Azure to Bicep, with backup and disaster recovery modules, and documented the scripts for junior engineers.

AI that extends an engineer’s reach

I want to give engineers the tools to do work that used to feel beyond their reach. AI can help them explore an unfamiliar system, draft a script or spot a pattern in a large set of reports. I use it myself and teach the team to use it. The engineer still needs to understand the answer, test the change and own the result.

Melbourne changed my view of automation

When I moved to Melbourne in 2021, I encountered entire line-of-business applications written in PowerShell to manage Active Directory. Until then, I hadn’t seen it used on that scale. It expanded my idea of what automation could do, and made maintainability just as interesting to me as capability.

Enabling new platforms

I built and configured a Kubernetes test environment for SAP integration work, then handed it over for testing. I also created a production Power Platform environment for a Centre of Excellence. These were infrastructure foundations and handovers, not ownership of the complete application platforms.

Small tools matter

At a previous employer I wrote PowerShell that recovered around 30,000 deleted emails for a client. Automation earns its place by solving a real problem. Sometimes that is a reusable deployment module; sometimes it is a focused script that gets someone’s work back.

Credentials

Microsoft certified, and recognised by peers

Azure architecture and administration certifications, a Windows Server foundation, and years of community work with Microsoft’s Windows Insider programme.

A foundation that keeps developing

  1. 1
    Windows Server

    MCSA 2016 · earned in 2018

  2. 2
    Azure administration

    AZ-104 · renewed through October 2027

  3. 3
    Azure architecture

    AZ-305 · renewed through October 2027

Azure Fundamentals · AZ-900

March 2024. The foundation for the two Azure certifications above.

Windows Server and study

MCSA: Windows Server 2016 (2018), building on earlier MCSE, MCSA and MCP certifications. I completed a two-year Diploma in IT Networking at Varsity College in 2006.

Community

Microsoft MVP, Windows Insider, 2016 to 2018. Windows Insider since 2014. I also volunteered as an adviser at SeniorNet from 2017 to 2019, helping people become more comfortable with technology.

Putting the learning to work

The useful part of study is bringing it back to the estate: understanding Azure design choices, explaining them to engineers and building deployments other people can maintain. I first earned AZ-104 in July 2024 and AZ-305 in August 2024, and have kept both current.

Selected work

Decisions, delivery and what changed

Six case studies in infrastructure leadership: decisions under pressure, practical AI, team development and dependable delivery.

What connects the work

Each example involves making a difficult situation easier for other people to manage: sharing knowledge, planning a migration, simplifying automation or keeping an incident moving toward recovery. The technical fix and the way the team works both matter.

How these are written

These are short accounts of work I led or carried out with the team. They describe the starting point, my responsibility and what changed. Clients are anonymised, and the figures are kept to the scope needed to understand the work.

How I think and lead

Build capability. Reduce dependence.

The estate should become easier to operate, and the team more capable of operating it. I judge an improvement by what it makes possible for the people who come after me.

Three questions behind a change

  1. 1
    Who depends on it?

    Start with the people and the service.

  2. 2
    Who can support it?

    Build understanding across the team.

  3. 3
    What will we do differently?

    Turn incidents into changes in practice.

Greatness is a choice

Standards show up in ordinary work: keeping the roadmap useful, documenting a change and following through on something I said I would fix. That consistency helped me earn the trust of experienced engineers when I became their lead.

Call, don’t message

When something is urgent or tangled, I pick up the phone. A conversation gives people room to explain the problem and ask questions. During a difficult incident, I stay available to stakeholders while we work through the technical cause.

Radical responsibility

The buck stops with me. I’m responsible for the direction I set, the support the team gets and the work we put in front of a client. When something goes wrong, I want to understand it, help put it right and make the learning available to everyone.

Give engineers more reach

I’m openly pro AI when it makes engineering better. Used well, it helps people investigate faster, build a useful first draft and take on harder work. I want the team to gain those abilities together, with the confidence to question an answer as well as use it.

Be clear when the answer is no

Moving new server deployments toward Windows Server 2025 meant asking application teams to do more testing. I explained the longer-term lifecycle and security reasons, listened to the pushback and kept the direction clear. Good leadership includes explaining a decision that creates work for someone else.

Beyond the day job

Leading people outside of work too

Community service, conversations, software and music. Different parts of my life, each worth doing properly.

Different ways of making a contribution

  1. 1
    Community

    Board service and conversations through The XboxCast.

  2. 2
    Software

    Products through Southlight I/O and a rebuilt podcast website.

  3. 3
    Music & writing

    Made By Humans and personal essays, each with its own home.

Board member · Southern Cross Church

From 2023 to 2025, I served on the board, reviewing finances and taking part in decisions about remuneration, equipment and events. It was a different form of responsibility from running infrastructure: considering how money and practical decisions supported the people and activities of the church. I contributed as one member of the board, with decisions made together.

Co-host · The XboxCast

Since 2017, I’ve helped plan, record and publish a technology and gaming podcast. I also rebuilt its website from the ground up when WordPress no longer met our needs. It’s an example of being willing to make a substantial change when the existing approach has stopped serving the people using it.

Founder · Southlight I/O

My privacy-first software studio is where I build products with AI-assisted development. It gives me room to work through an idea, make the implementation decisions and turn it into something people can use.

Practice beyond work

I’ve completed 75 Hard three times. I also write at kyledunkerley.com, where there’s space for the personal stories, ideas and interests that don’t fit a professional profile. Both are part of how I keep choosing work that asks something of me.

Made By Humans

Music with energy, made to be used

My independent music project: instrumental rock and metal with electronic and cinematic elements. Separate from Southlight I/O, and a place for a different kind of creativity.

InstruMETAL · Five-track EP

  1. 1
    Instrumental

    Guitars, drums and electronic textures.

  2. 2
    Cinematic

    Hope, tension, struggle and victory.

  3. 3
    For creating

    Music for listening, working and making things.

Why I started

I wanted an energetic alternative to lo-fi background music: instrumental music with enough character to listen to closely, and enough room for someone to work, stream or create alongside it. Made By Humans grew out of wanting that music to exist.

The sound

InstruMETAL is a five-track EP that moves through hope, tension, struggle and victory. Guitars and drums share space with electronic textures and more cinematic passages. The first single, Victory Spurs Us Onwards, captures the feeling of a hard-won finish.

For other creators

The project’s purpose is a library of royalty-free rock and metal for streams, videos and other creative work, as well as listening in its own right. My introduction explains the music, its intended use and the thinking behind it.

Why the name matters

Made By Humans reflects my belief that making things has value in itself. Choosing the notes, working through an idea and putting something personal into the world are part of the point.

Career and perspective

Choosing the difficult move

From South Africa to New Zealand, then Melbourne. Each move asked me to start again, learn quickly and take on a little more responsibility.

A career built through changing responsibility

  1. 1
    South Africa

    A foundation in hands-on support and networks.

  2. 2
    New Zealand

    From NOC support to on-site ownership and client relationships.

  3. 3
    Melbourne

    From WinTel administration to leading infrastructure engineers.

Leaving home

Leaving South Africa for New Zealand was a big change. It meant leaving my homeland to work toward a better future. I carry that willingness into the rest of my life: a difficult decision can be worth making when it creates room to grow.

Prophecy · Starting in support

I joined Prophecy Networks in March 2011 in Level 1 NOC support. A Windows 8.1 and Office 365 rollout at Napier Port led to an ongoing on-site support role because of how I handled the project.

Napier Port · Growing responsibility

My responsibilities kept expanding within that one role: Level 1, 2 and 3 support, Active Directory, Office 365 and infrastructure scripting. I stayed on site until 2018. It taught me to take ownership of the whole environment as well as the immediate support request.

Prophecy · Microsoft Solutions Specialist

In 2018 I returned from the on-site assignment to Prophecy as a Microsoft Solutions Specialist. I worked with clients on Azure AD and identity and access management solutions, bringing what I had learned running an environment into conversations about what they needed next.

LANtech · August 2019

As a System Administrator in a traditional MSP, I was the technical contact for smaller clients, often around 15 people per site. I covered Microsoft 365, laptops, licensing and infrastructure support, and contributed to Statements of Work. Building confidence meant understanding each client’s environment and following through.

Melbourne · 2021

I joined DXC Technology as a contract WinTel System Administrator in January 2021 and became a team lead that August. Seeing entire Active Directory management applications built in PowerShell expanded my view of automation. I went on to lead four engineers across a hybrid estate, with the internal title of Associate Manager from 2026.

PIR-01 · Case study

Rebuilding a team around its engineers

Major staffing changes folded our Windows infrastructure function into a wider end-user computing group.

From individual knowledge to shared capability

  1. 1
    Set direction

    A practical roadmap alongside the ticket queue.

  2. 2
    Learn through work

    Mentoring, shared notes and clear responsibilities.

  3. 3
    Share ownership

    Engineers take on server work and end-to-end patching.

Situation

I was given one onsite and two offshore engineers and had to build a working team around them.

What I did

Introduced weekly sprints and a shared Kanban board, moved documentation to living notes engineers could update, and taught Azure and Infrastructure as Code on the job. The roadmap gave us a shared direction alongside the immediate demands of the ticket queue.

The harder part

As a younger lead, I had to earn the confidence of more experienced colleagues. Laying out the work methodically and following through showed that I was committed to improving our domain. The title alone could not do that.

What I learned

I enjoy seeing people take on work they could not have handled before. Giving someone a clear direction and the support to learn builds more lasting capability than keeping every difficult task for myself.

PIR-02 · Case study

Moving production through a business separation

A business separation meant new infrastructure and a new domain across Australia and New Zealand. My first major assignment here.

The delivery sequence

  1. 1
    Build

    Standards and installation on the new estate.

  2. 2
    Move

    Stakeholder coordination, outage windows and cutovers.

  3. 3
    Retire

    Structured decommissioning of replaced systems.

Situation

New servers, a new domain and a hard deadline, with the business still running on the old estate.

What I did

Owned delivery end to end apart from procurement: build standards, installation, outage windows, cutover plans and structured decommissioning. That included coordinating stakeholders so the technical work and the business timetable stayed connected.

Managing the change

The challenge was carrying out the separation while people still depended on the existing estate. Planned outage windows and a clear cutover sequence gave the work structure. The servers were one part of a wider operational change.

PIR-03 · Case study

Automation the whole team can read

Advanced PowerShell that only its author could safely change is a risk, however clever it is.

What changed in the automation

  1. 1
    Before

    Complex scripts and knowledge held by one person.

  2. 2
    Change

    Bicep modules, simpler PowerShell and documentation.

  3. 3
    After

    A clearer route for other engineers to maintain deployments.

Situation

Azure deployments depended on complicated scripts and one person’s memory.

What I did

Moved deployments from ARM templates to Bicep, including modules for backup and disaster recovery. I simplified the PowerShell and documented it for junior engineers, then taught the concepts alongside the work.

The design decision

Seeing whole business applications built in PowerShell had shown me what automation could achieve. In a shared estate, that power needs to be understandable. The useful question is whether another engineer can read a deployment, change it and support it.

PIR-04 · Case study

A restored server that wouldn’t rejoin the domain

A Windows Server 2012 machine in Azure crashed after updates and had to be restored.

Restoring the service, step by step

  1. 1
    Restore the VM

    The machine returns, but cannot authenticate.

  2. 2
    Investigate trust

    Work through domain and computer-account issues.

  3. 3
    Restore access

    Script the account reset and record the incident.

Situation

After the restore the server could not authenticate. Domain trust, password age and the computer account were all in question while stakeholders waited.

What I did

Stayed on the incident bridge, answered stakeholder questions and continued the technical investigation. I worked through the domain trust and computer-account issues, then scripted a computer-account reset to restore access.

Leading during the incident

People needed both a working service and someone who could explain where the investigation stood. I kept doing both as the work continued into the early morning. Staying with the problem mattered more than offering a quick answer before we understood it.

PIR-05 · Case study

When the cutover didn’t go to plan

A three-week Hyper-V to VMware migration at a manufacturing site. An unplanned database-server outage changed the cutover, and the way we approached the next database move.

The three recovery options

  1. 1
    Stop at 20%

    Lose scan progress; no guarantee the database lock releases.

  2. 2
    Run in DR

    Resume work, but risk missed orders when reconciling new records.

  3. 3
    Continue to migration · chosen

    Adjust settings and complete the move, agreed with the site manager and DBA.

Roughly six hours of interruption. Operators used paper reporting and intake.

The work · April–May 2025

I owned the migration of 21 VMs end to end over three weeks: coordinating outage windows, cutovers and health checks as we moved from three physical hosts onto two new VMware hosts. The largest SQL server had about 3.5 TB across five drives and supported the site’s main production application. Most machines followed a sequence of pre-scan, planning, re-scan and cutover.

When preparation became an incident

During the database server’s pre-scan, the conversion tooling locked the database and the production application became unavailable. The same approach had worked on other VMs. Operators switched to paper reporting and intake while we worked through the interruption, which lasted roughly six hours.

Three options, each with a cost

The pre-scan was about 20% complete. Stopping would lose that progress without a guarantee that the database lock would release. Bringing the server up in disaster-recovery mode could let the site work, but merging the new records back afterwards risked missed orders. The DBA was concerned about that reconciliation. The third option was to adjust the conversion settings and continue through to migration.

Delivery and follow-through

The database server was migrated and the application returned to service. I stayed responsible for completing the wider migration and the follow-up work. That included retiring the old systems; monitoring also needed to reflect the changed network interfaces. A successful cutover still leaves operational work to finish.

What I take from it

I was accountable for a change that interrupted production, and for getting it through to completion with the site manager and DBA. The lasting improvement was changing our approach to the next database move.

PIR-06 · Case study

A useful finding is the start of an investigation

AI helped surface a pattern in backup reports. An engineer established what needed changing. A separate patch review showed why that second step matters.

AI suggests. Engineers verify.

  1. 1
    Find a pattern

    Copilot analysis across 1,081 backup reports.

  2. 2
    Check the evidence

    An engineer investigates the reported failures.

  3. 3
    Make a verified change

    Firewall remediation, followed by successful backup results.

The question I gave the team

I used Copilot to analyse backup reports and identify repeated failures, then passed the findings to an engineer with a request to check whether they were correct and what we could do about them. The output gave us somewhere to start investigating.

What the engineer found

The investigation led to a firewall change. The engineer recorded the remediation, and subsequent backup results showed the affected jobs completing. My role was to set up the investigation and follow through; the engineer did the technical remediation.

When the AI findings did not hold up

In a separate review, Copilot flagged supposedly missing patches. The engineer identified superseded updates and findings for applications that were not installed on those servers. Treating the generated list as an instruction to patch would have skipped the most important part of the work.